 Prompt Workshop
Why it is written this way
Tap a block to see its paragraph
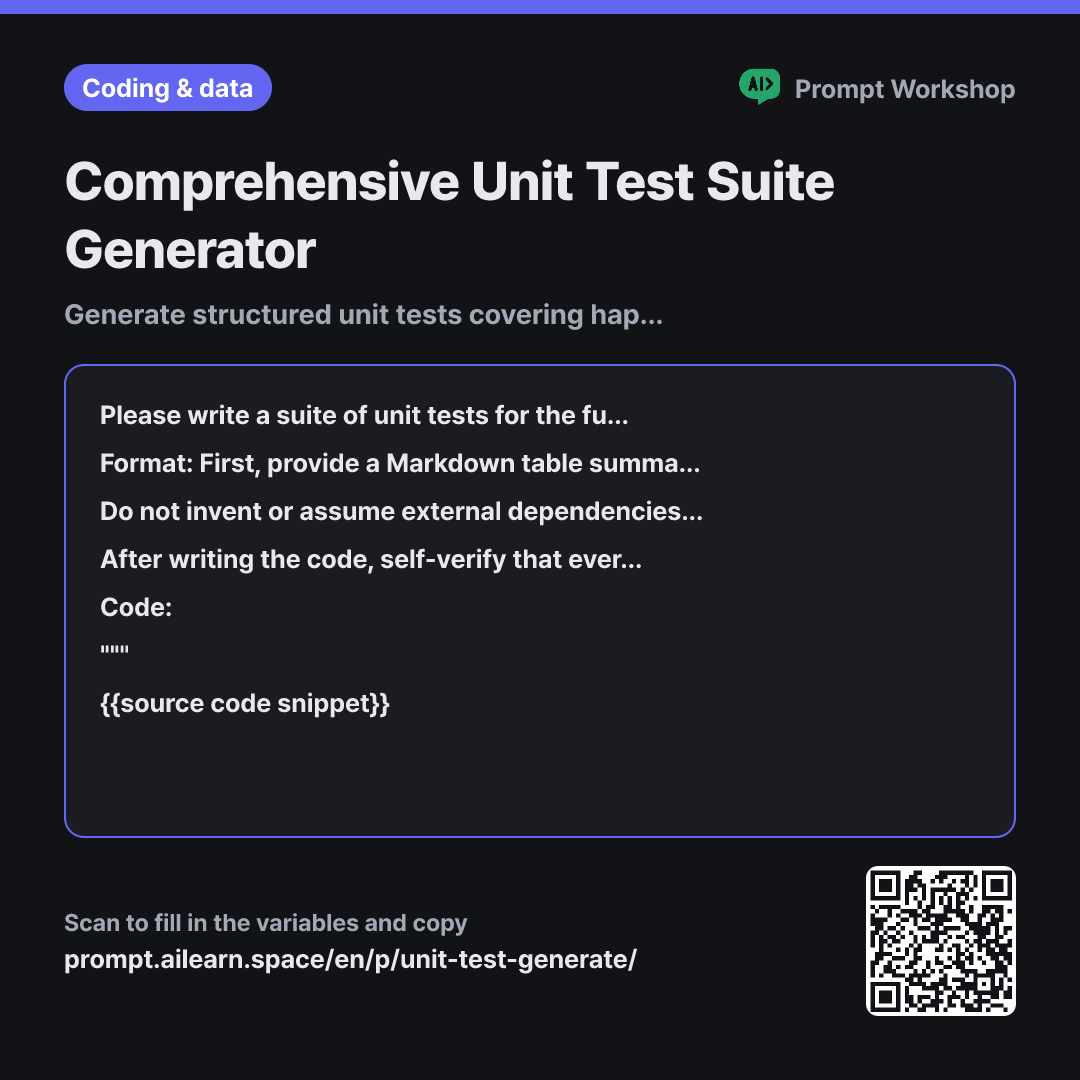
Please write a suite of unit tests for the function below using {{testing tool software}}. Categorize the test cases into three distinct groups: "Happy Path, Boundary/Edge Cases, and Failures/Exceptions". Only include cases that genuinely alter the execution branch or result.
Format: First, provide a Markdown table summarizing each test case before writing any code. The table columns must be: "Category | Input Values | Expected Result | Rationale for Case". Next, generate the actual test code in the exact order of the table. Name each test function descriptively so the intent is immediately clear just by reading its name.
Do not invent or assume external dependencies, configurations, or helper functions not shown in the snippet. If mocks are necessary, stub them cleanly and add comments explaining what was mocked. Limit the entire suite to no more than 12 tests, and consolidate repetitive parameterized checks into single parameterized tests where appropriate.
After writing the code, self-verify that every test strictly validates what is stated in your table. If any test would pass trivially regardless of code modifications (a tautological test), remove it and state your reason for removal in a final one-line summary.
Code: """ {{source code snippet}} """
- Material What the AI needs to know ×1
- Work What to do, and how ×2
- Output What comes back, in what shape ×2
When you prompt an AI with a generic "write tests for this code," it typically churns out ten nearly identical happy-path tests. Seeing green checkmarks on repetitive inputs gives a false sense of security while completely missing the critical boundaries and exceptions where actual bugs live.
Read the full explanation · 4 paragraphs
The Task structure addresses this directly. By demanding three explicit buckets—"Happy Path, Boundary/Edge Cases, and Failures/Exceptions"—the AI is forced to re-read every conditional branch in your code. In the example above, threshold values like $30 and $50, as well as invalid inputs like 0 or negative numbers, get surfaced immediately.
Requiring the table Format before the code ensures proper review hierarchy. Reviewing raw test code often leads to skimming syntax, whereas reviewing a test plan table makes missing edge cases instantly obvious. The "Rationale" column forces the AI to eliminate redundant assertions.
The 12-test ceiling is intentional. Without a constraint, the AI generates dozens of bloated test variations that clutter the test suite. A strict limit forces prioritization of high-risk boundary cases over trivial positive cases.
The final self-verification step eliminates tautological tests (tests that pass no matter how broken the implementation is), a frequent issue in AI-generated test suites. Enclosing the target code in """ delimiters prevents internal code strings or comments from being misinterpreted as prompt instructions.
Unfamiliar terms? See Aha AI: output-format, hallucination
Compared with a bad example
Write unit tests for this function
(paste code here)
This produces a handful of trivial happy-path tests that pass easily. Crucial boundary values and exception handling are omitted, and the AI often invents non-existent fixtures or configuration files, preventing the code from running out of the box. Green checkmarks from shallow tests create dangerous false confidence.
Variations
Finding Missing Test Coverage
Use this when you already have existing tests. Generating a missing-scenario table first prevents duplicate or low-value tests from bloating your codebase.
Show prompt
Below is a function alongside its existing test suite. Do not write new tests immediately. First, output a table listing only the untested edge cases, missing failure modes, or uncovered branches. Use the columns: "Untested Scenario | Why It Is Needed | Risk Level (High/Med/Low)". Then, provide {{testing tool software}} test code for only the top 3 highest-risk scenarios.
""" {{source code snippet}} """
Debugging a Failing Test Case
When pasting a failing test, AI models tend to tweak the assertion to force a pass rather than investigating the root defect. This instruction blocks that shortcut.
Show prompt
The {{testing tool software}} test below is failing. First, analyze whether the implementation code or the test assertion itself is incorrect, and provide the technical reasoning behind your conclusion. Do not blindly modify the expected value just to make the test pass.
""" {{source code snippet}} """
Model notes
Always run generated tests locally. Untested AI code often looks syntactically plausible but fails upon execution due to subtle mock or assertion mismatches.
Assertion methods and syntax vary significantly across different testing framework versions. If the output uses deprecated or unfamiliar syntax, re-prompt by specifying: "I am using {{testing tool software}} version X.X."
Last updated 2026-09-02 · Found a mistake? Let us know